
Global inference network
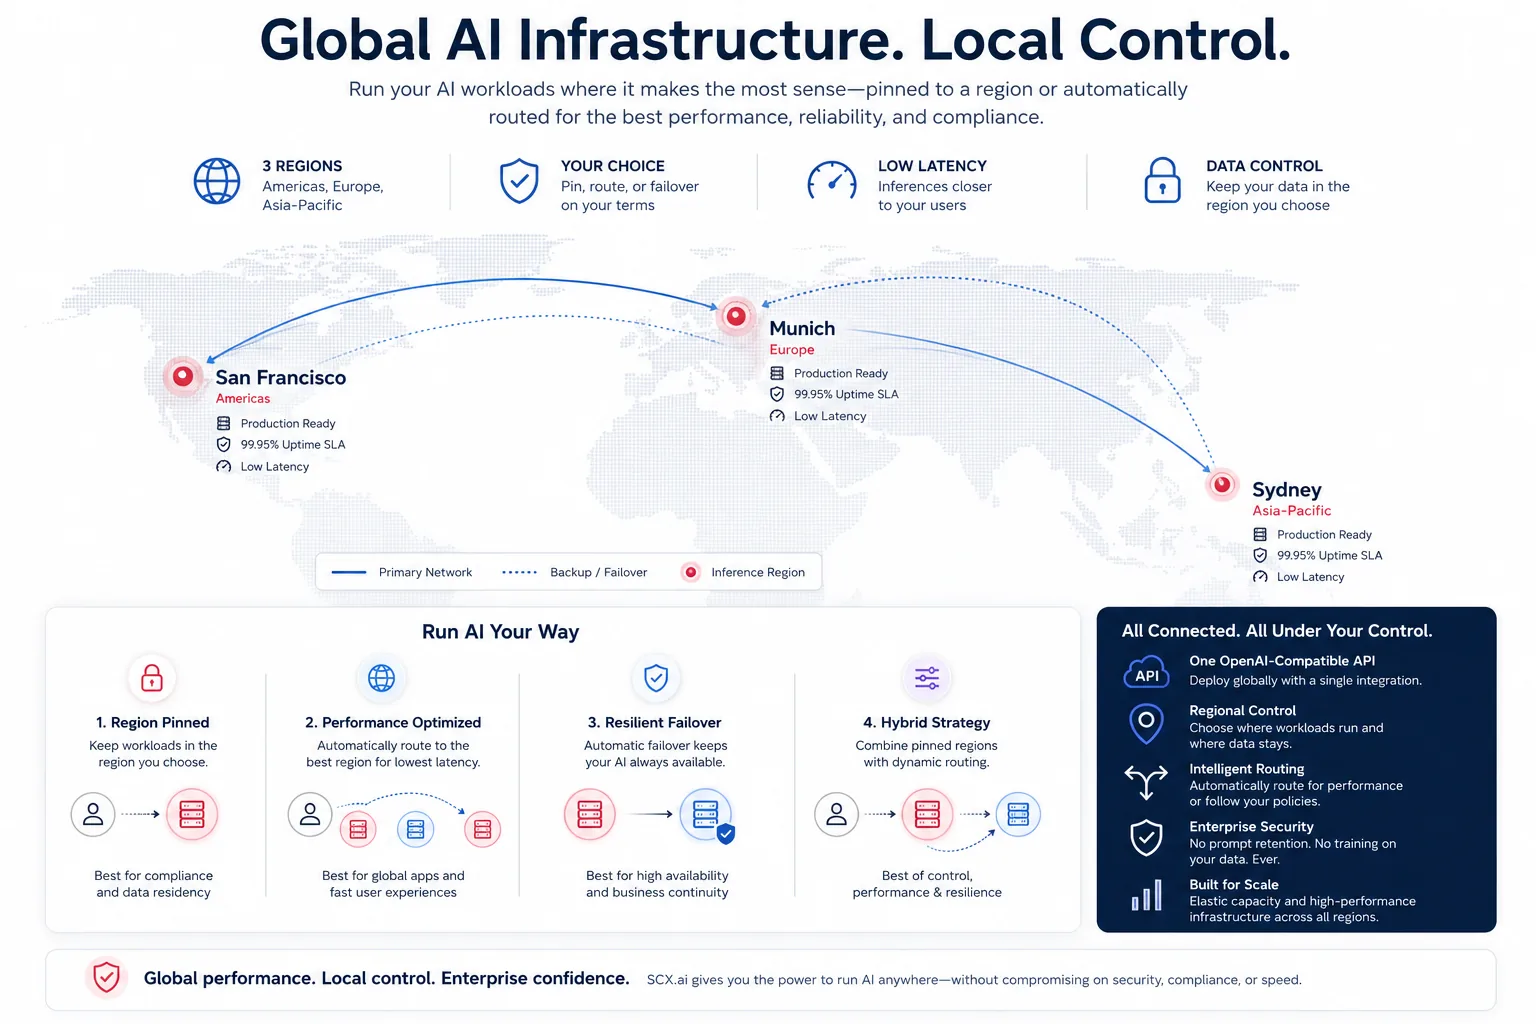
Global AI infrastructure.
Local control.
Run AI where it makes the most sense for your business. Pin sensitive workloads to a region, route public traffic for latency, and fail over automatically without redesigning your application.
Why a global inference network
AI infrastructure needs regional intelligence
AI workloads increasingly operate across multiple regulatory environments, customer geographies, and latency requirements. SCX.ai deploys inference where performance, compliance, and operational requirements align.
Regional control
Choose exactly where workloads run.
- Region-pinned inference
- Data locality alignment
- Geographic workload separation
- Enterprise governance support
Performance optimization
Deliver low-latency AI experiences globally.
- Local inference routing
- Reduced latency
- Optimized throughput
- Faster customer response times
Built-in resilience
Maintain availability across regions.
- Regional redundancy
- Intelligent failover
- Multi-region infrastructure
- Operational continuity
Operationally simple
One API across the entire network
Deploy globally through a single OpenAI-compatible interface while controlling routing, residency, and inference behavior at the workload level.
from openai import OpenAI

client = OpenAI(
    api_key="scx_...",
    base_url="https://api.scx.ai/v1",
)

# Pin to a specific region
resp = client.chat.completions.create(
    model="MAGPiE",
    messages=[{"role": "user", "content": "Hello"}],
    extra_headers={"x-scx-region": "syd"},  # or 'sfo', 'muc', 'auto'
)

print(resp.choices[0].message.content)
Routing on your terms
Pin to syd, sfo, or muc—or pass auto and SCX routes to the optimal region for latency and availability.
- No multi-cloud engineering
- No region-specific SDKs
- No bespoke orchestration logic
- Stable, OpenAI-compatible interface
Security & data control
Regional control without losing security
Global infrastructure usually means new data-exposure and governance complexity. SCX.ai keeps the controls explicit.
Region-aware workloads
Pin inference, embeddings, and document handling to specific regions. Data locality is enforced, not asked for.
No prompt retention
Prompts and outputs are processed and discarded. No silent logging for review, fine-tuning, or analytics.
No training on customer data
Your data is never used to train, fine-tune, or improve our models or anyone else’s.
Infrastructure isolation
Tenant isolation across all regions, with role-based access, SSO, and audit-ready logs by default.
Resilience & failover
Enterprise resilience built into the network
Most AI vendors don't make failover, capacity balancing, or regional resilience explicit. SCX.ai does.
Intelligent failover
Workloads are redirected automatically during outages or congestion.
Capacity balancing
Inference distributes intelligently across regions when one comes under pressure.
Business continuity
Keep AI operations running through regional disruption events.
Use cases
Built for global enterprise workloads
Financial services
Regional compliance with low-latency inference for trading, risk, and customer flows.
Healthcare
Geographic control for sensitive workloads and patient-adjacent data.
SaaS platforms
Responsive customer experiences from regions closest to each tenant.
Legal & enterprise search
Inference confined to controlled jurisdictions for matter-sensitive work.
Customer support AI
Route conversations to the nearest low-latency region for natural exchanges.
Government & defense
Mission-critical inference inside controlled jurisdictions, with strict residency, isolation, and audit-ready trails for regulated workloads.
Deploy AI globally without losing control
SCX.ai combines global AI infrastructure with enterprise-grade control over security, routing, performance, and resilience.